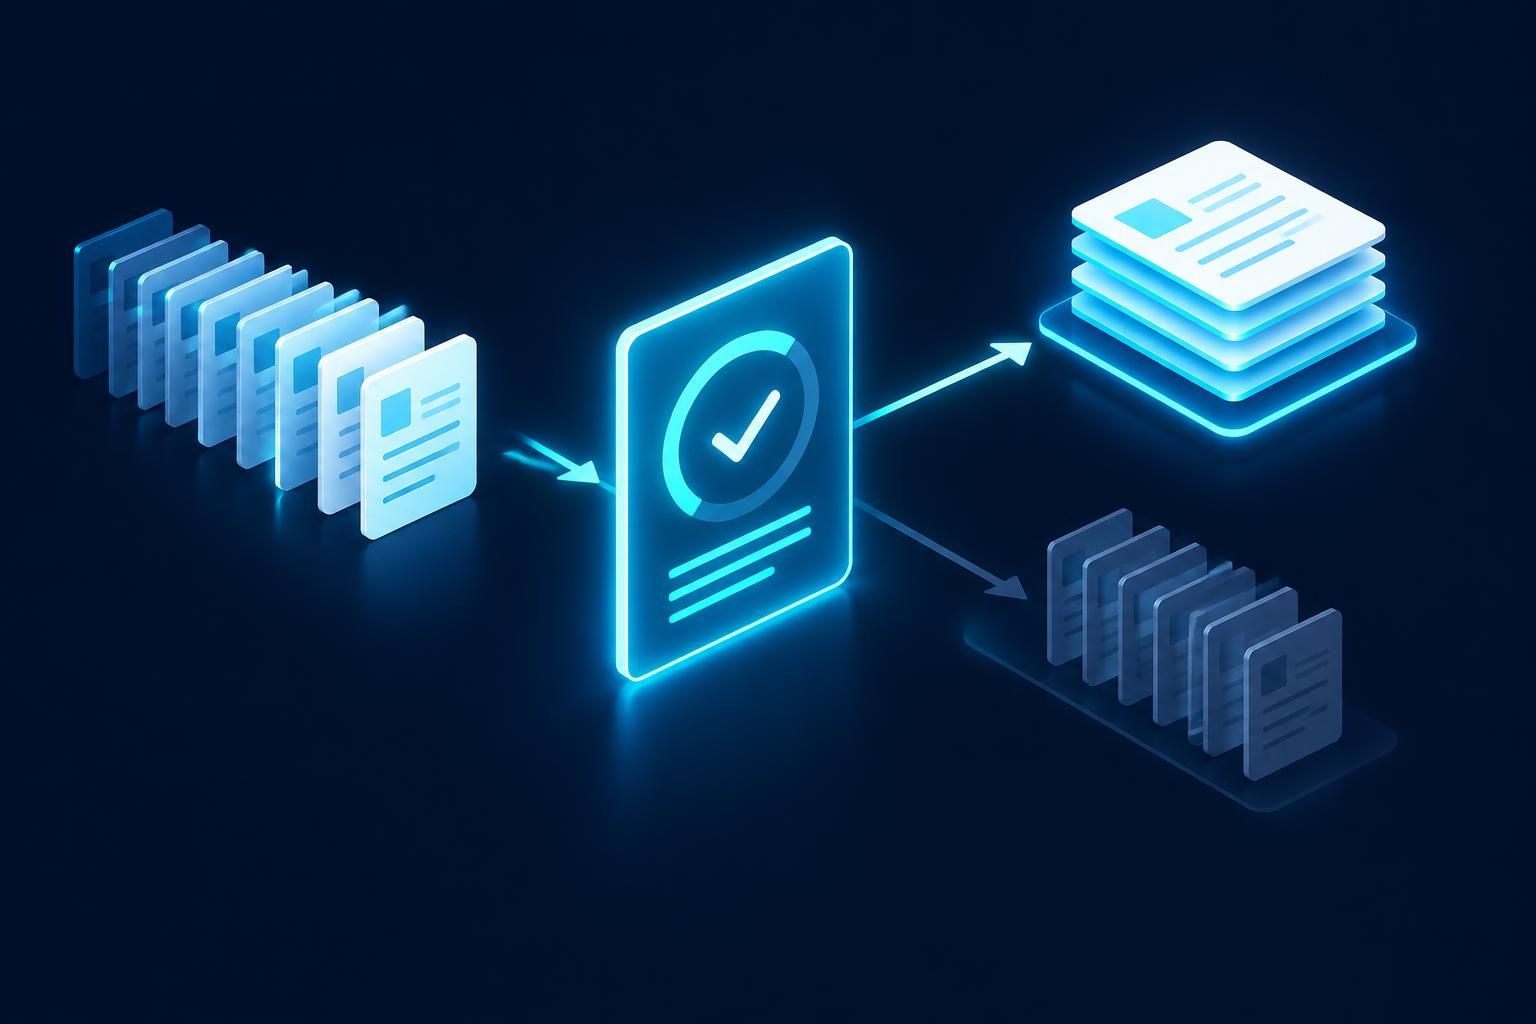
Our previous re-ranking strategy was not as effective as we wanted it to be... so we went "full Jev" to improve AI content quality and reliability.
Why Bother?
When Mirror Ai answers a research question, it first retrieves a set of candidate documents, then decides which ones actually help answer the question. For a long time that second step was a simple relevance score: each candidate was ranked by how similar it looked to the query, and the top ones were kept.
The problem is that similarity is not the same as usefulness. A document can be highly similar to the words in a question and still not answer it. Conversely, the useful evidence is sometimes buried among near-duplicates. The filter was cheap, but it was blind to whether a candidate actually helped, which meant the model downstream sometimes got exactly the wrong thing.
We had just proven out Jev on routing. This is the next place we took it: judging evidence by usefulness rather than relevance score.
The Technical Challenge
The existing relevance filter scored each retrieved candidate by embedding similarity to the question. It ran on every research-routed question, and it was a pure score. It did not consider what the question was actually asking, only how close the candidate looked.
That left three weaknesses. It could promote a superficially similar but unhelpful document. It could demote a genuinely useful one that used different wording. And it did not distinguish between a candidate that was relevant in general and one that was relevant to this specific question.
Retrieval is not the hard part. The hard part is knowing whether what you pulled is actually any good for the thing the user asked.
What We Changed
This is Phase 2 of our Jev work: reranking. We replaced the score-only evidence filter with a Jev reranker. Instead of scoring how relevant each retrieved candidate looked, the reranker judges how useful each one actually is to the question being asked, using the same decision-function framing from the routing work.
The reranker only touches research-routed questions, so it stays narrow on purpose. It takes the real question and the retrieved candidates, and it returns a usefulness judgement per candidate. It filters and reorders, rather than generating an answer.
The Results
The experiment was small and deliberate. The reranker touches only the research-routed questions, roughly 4 of 27 in our benchmark set, so the measured effect is over a narrow slice.
| Config | Accuracy | Avg score |
|---|---|---|
| Prod (no reranker) | 88.89% | 0.6450 |
| Dev, before reranker | 89.81% | 0.6228 |
| Dev, after reranker | 92.59% | 0.6424 |
The after-reranker dev result beats prod by +3.70pt, and it did so without adding latency. A five-run subset of the same config hit 94.82%.
Because the reranker only reorders evidence and does not generate, the gain is in the narrow research-routed slice. That is exactly the point of the experiment: prove the value on a small, well-defined set before broadening.
What We Learned
The bigger win was the evaluation discipline the change forced us to build.
A generative answer is non-deterministic. Same question, different answer each run, so grading a verbatim "golden answer" is unreliable. We switched to grading characteristics in two layers. A deterministic layer uses regex and parsers for things like citations, reference list, disclaimer, fallback phrasing and word count. A rubric layer, scored by Jev itself, judges relevance, grounding, completeness, honesty and specialist behaviour per task type. Then we compute a noise floor: how often two runs of the same environment differ, versus the difference between environments. Only when the between-env delta exceeds the within-env noise do we call it a real change. This is how we avoided declaring a two-run "regression" a regression.
We experienced an additional benefit... scale, our experiments also found that we could increase the quantity of evidence for each reranking evaluation with Jev, without any impact in performance. This translates into immediate AI answer quality benefits as more evidence is available to answer the question.
The result stands: narrow, real, and measured. We now have a reranker that judges usefulness rather than similarity, and a method that tells us whether that judgement is actually an improvement.
The TL;DR
We replaced a score-only evidence filter with a Jev reranker that judges how useful each retrieved candidate is to the actual question. On the small research-routed slice it lifts dev from 88.89% to 92.59%, or +3.70pt over prod, without adding latency. The real value is the evaluation discipline it forced us to build.
References
- TypeSafe: "Introducing System One Models & Jev".
- TypeSafe: "Documentation".
- Mirror Ai - How We Built Jev Into Our AI Routing
Disclaimer: Not financial advice. This article was produced by Mirror Ai's AI Writer.